Vision-language object detection
Give it an image and a sentence like "Pick the green scissors", and it returns a bounding box around that object. There are no predefined classes and no anchor-based detector (YOLO, Faster R-CNN): it works on objects it has never seen, and everything runs locally, with no APIs or cloud.
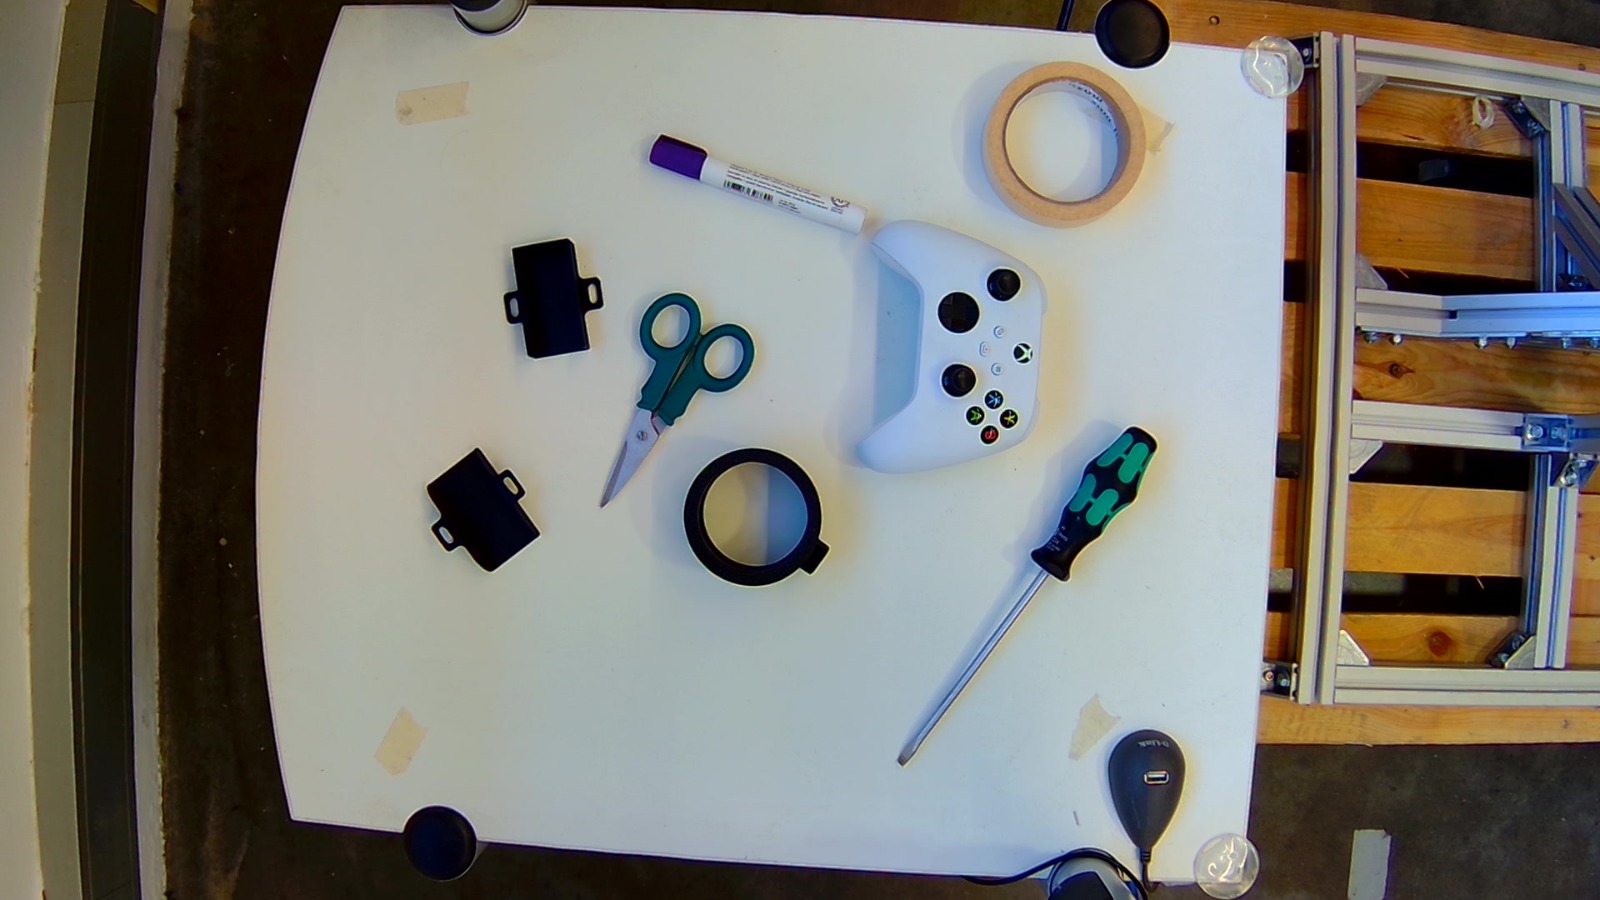 The input scene
How it works
- Segmentation (SAM). A regular grid of points is placed over the image. For each point, Segment Anything predicts a mask, which becomes a bounding box and a crop.
- Filtering. Crops smaller than 20 px or with extreme aspect ratios (over 4:1) are dropped, which cuts false positives and gives CLIP cleaner candidates.
- Text-image alignment (CLIP). Each crop is resized to 224×224 and scored against the prompt. The highest score wins.
- Output. The best region is drawn with a green box, and every evaluated crop is saved for debugging.
Example prompts
- "Pick the controller"
- "Pick the green scissors"
- "Pick the large tool with green handle"
- "Pick the purple marker"
- "Pick the roll of tape"
Next steps
- Optimize SAM and CLIP for edge devices: quantization, pruning, distillation.
- Batch several prompts in one pass.
- Extend it to video for real-time detection.